👋 I'm Matthias Plappert. Learn more about me and my background. If you enjoy what you read, subscribe—new posts land straight in your inbox.

Two types of AI agents

| 4 min read | Permalink

Someone recently let Meta’s Muse AI agent sell a keyboard on Facebook Marketplace for him. Muse agreed to a lowball price, gave a buyer the seller’s home address, and replied “Yep I’m here!” when he wasn’t available. It didn’t check with the seller about any of it until the buyer was already standing outside, and all of it was done under the seller’s name and account.

Muse owned the sale (it has its own computer and works independently), but it put the seller’s name on it. He ended up accountable for actions he didn’t direct or fully understand.

This points to something more general: There will be two very different types of AI agents, and what separates them is who owns the work:

  1. Personal assistant. This agent will be co-located with your personal data and will help you do your work. It can act, but it will do so on your behalf and under your name. You retain ownership of this work.
  2. Virtual employees. These agents will be separate entities; they will have their own name, computer and accounts. They work for you but they own their own work; you hand them a responsibility, not a task.

Personal assistants are close to what people today already use ChatGPT and Claude for. But they will be much more capable: Instead of being constrained to a chat window, they will have access to your files, emails and calendar and can perform actions directly on your behalf.

Virtual employees will look a lot like human employees: You give them their own computer, provide them with a company email account, and invite them to Slack or Teams. From this point on, they own their area of responsibility, and you manage them by outcomes rather than checking every step. If they need access to something, you forward them an email, add them to a Google Drive folder, or send them a file via Slack just like you would with a human employee. Similar to human employees, you might hire multiple agents with different roles and personalities and you might fire them if they don’t work out.

The two types differ in the following ways:

Personal assistantVirtual employees
OwnershipYou own the workAgents own their own work
AccountsUses your existing accountsUse their own, dedicated accounts
DataCo-located with your personal data (file system, emails, calendar, …)Have their own file system and access to shared data
IntegrationDeep OS-levelSeparate VM
OversightApprovals and permissionsTrust, scope and outcomes; may get fired
Number of instancesOneMany

I expect that almost every person will have one, and only one, personal assistant agent. Some people will have a few virtual employees and even fewer will have effectively a whole company of virtual employees. More commonly though, existing companies will start to hire these, and they will work alongside human employees. Lastly, your personal assistant will likely help coordinate your virtual employees.

Some of this is already visible today:

  • Apple is clearly building the personal assistant with Apple Intelligence and its semantic index for accessing all your personal data.
  • Meta’s Muse, while very cool and well-executed, ultimately is a confused product: It is built like a virtual employee but acts like a personal assistant.

Here’s what I expect to follow:

  • By default, OS vendors (Microsoft, Google and Apple) will win on the personal assistant front for two reasons. First, they have full access to everything: your data, accounts, and apps already live on their platform, which is exactly what today’s chatbots lack. Second, since the work is yours (it happens under your name and you’re accountable for every action), personal assistants need strong guardrails and permissioning to avoid catastrophic outcomes, and only the OS vendor can enforce access control across the entire system.
  • Enterprise software will continue to do well: Virtual employees are just another seat, and enterprise access control and auditability are important. In fact, some consumers might start to use these enterprise tools to manage their personal virtual employees.
  • Legal liability for virtual employees is an open question and resolving it will be important: If they work independently and under their own name, who is liable for their actions?

Finally, if I were to build something in this space, I’d 100% focus on the second type. Competing with Apple, Google, and Microsoft on personal assistants will be very difficult, but virtual employees neutralize both of their advantages. They don’t need access to everything; they get access the way a new hire does, through forwarded emails, shared folders and Slack invites, which all enterprise software already supports. They also don’t need OS-level guardrails, since they act under their own accounts, and those are governed by the same access controls that already apply to human employees. In short, virtual employees are a level playing field whereas personal assistants are not.
Building a robotics research setup that lives next to my desk

| Permalink

A quick link post—the first of what may become a recurring thing here, where the title links straight to whatever I’m pointing you at.

Full disclosure: this one is my own work. I wrote up how I built a desktop robotics research setup for less than €5,000—roughly a tenth of what an equivalent setup cost us six years ago at OpenAI. It covers the full bill of materials, the hardware choices, and the custom software stack I wrote instead of reaching for ROS 2 or LeRobot.

If you’ve wondered whether serious robotics research is something an individual can do at home now, I think you’ll like it.

AI wants direct access to your data

| 8 min read | Permalink

I’ve recently made two large changes in the software stack that I use heavily in everyday life, and they were driven by AI: my note taking app and my personal finance app.

I’m still very fond of the apps that I’ve used for many years for each, but they had a key limitation that didn’t work for me anymore: They don’t expose their data directly. With AI, you really want to have direct, bidirectional (by which I mean both read/write) access to your data; and my new stack enables this.

Concretely, the switch was the following:

  • Bear → Obsidian for note taking.
  • YNAB → Moneten (a custom app I developed) for personal finance.

I’ll talk about both, because they cover two interesting use cases: note taking is mostly unstructured, messy data and personal finance is structured, organized data.

Note taking / unstructured data

I’ve used Bear for many years and I’m a big fan. The app is very polished, it works extremely well on Mac and iOS, and sync is fast and reliable.

However, it has one serious flaw: You cannot easily interact with its content programmatically. Bear stores all notes locally in a SQLite database. So reading from Bear is actually quite doable and I’ve had an MCP server for this for a while. But writing changes back into Bear is a non-starter. In fact, the Bear documentation explicitly warns users against modifying the SQLite database directly.

This turned out to be a severe design flaw for me: I want to be able to use AI tools to bidirectionally interact with my notes. I don’t want AI to write my notes (that defeats the purpose of note taking), but notes get messy and unorganized, and I’ve found that AI is amazing at cleaning up and organizing them. But I realized that I can’t do that with Bear, at least not straightforwardly.1

Very recently, Bear announced a CLI tool to make programmatic read/write access easier. They specifically cite AI tools as the main reason.

However, Bear’s data model is just fundamentally the wrong representation for notes. Notes are documents, and Bear uses Markdown. So my notes should just be Markdown files on disk. This really matters for using AI in practice: the agent can output a diff that gets applied to a text file, so updating a part of a note becomes extremely efficient and natural for agents. This isn’t possible for working with a database (or a CLI tool): The agent has to always output the whole note again.2

This is why I switched to Obsidian. It’s perfect for this. Obsidian just keeps around Markdown files on disk. They are the single source of truth and Obsidian is completely fine with other processes changing these files; it just monitors for changes and updates its UI.

Once I switched, I also realized that Claude Code / OpenAI Codex are very good at navigating folders of files. When they need to find things, they happily use ls, grep and find. So raw files aren’t just better for editing, but also for navigating the data.

I also got into the habit of using git for change tracking. Not in the sense that I commit my notes all the time when I make changes. But what I will often do looks something like this:

  1. I realize I want to do a clean-up / refactor using AI
  2. I git commit everything
  3. I ask AI to do the refactor
  4. I can use git diff to see exactly what was changed
  5. If necessary, I ask for corrections or revert
  6. Once I’m happy, I commit everything

This is an affordance that I get for free when using the file system. It works well and adds a safety net.

I’ve also built a simple linter that I run after AI changes to catch broken cross-reference links and other malformed data.

Personal finance / structured data

I’ve used YNAB since 2019 and I’ve categorized several thousand transactions for personal spend tracking. YNAB has served me really well over the years.

But my data lives on their server and I can only access it via a REST API. I want direct access to my data, and that means I want to have the raw database.

It also lacked a few features I cared about, like multi-currency support and investment tracking. So in the fall of 2025, I started developing my own personal finance app, which I call Moneten (a German word for money).

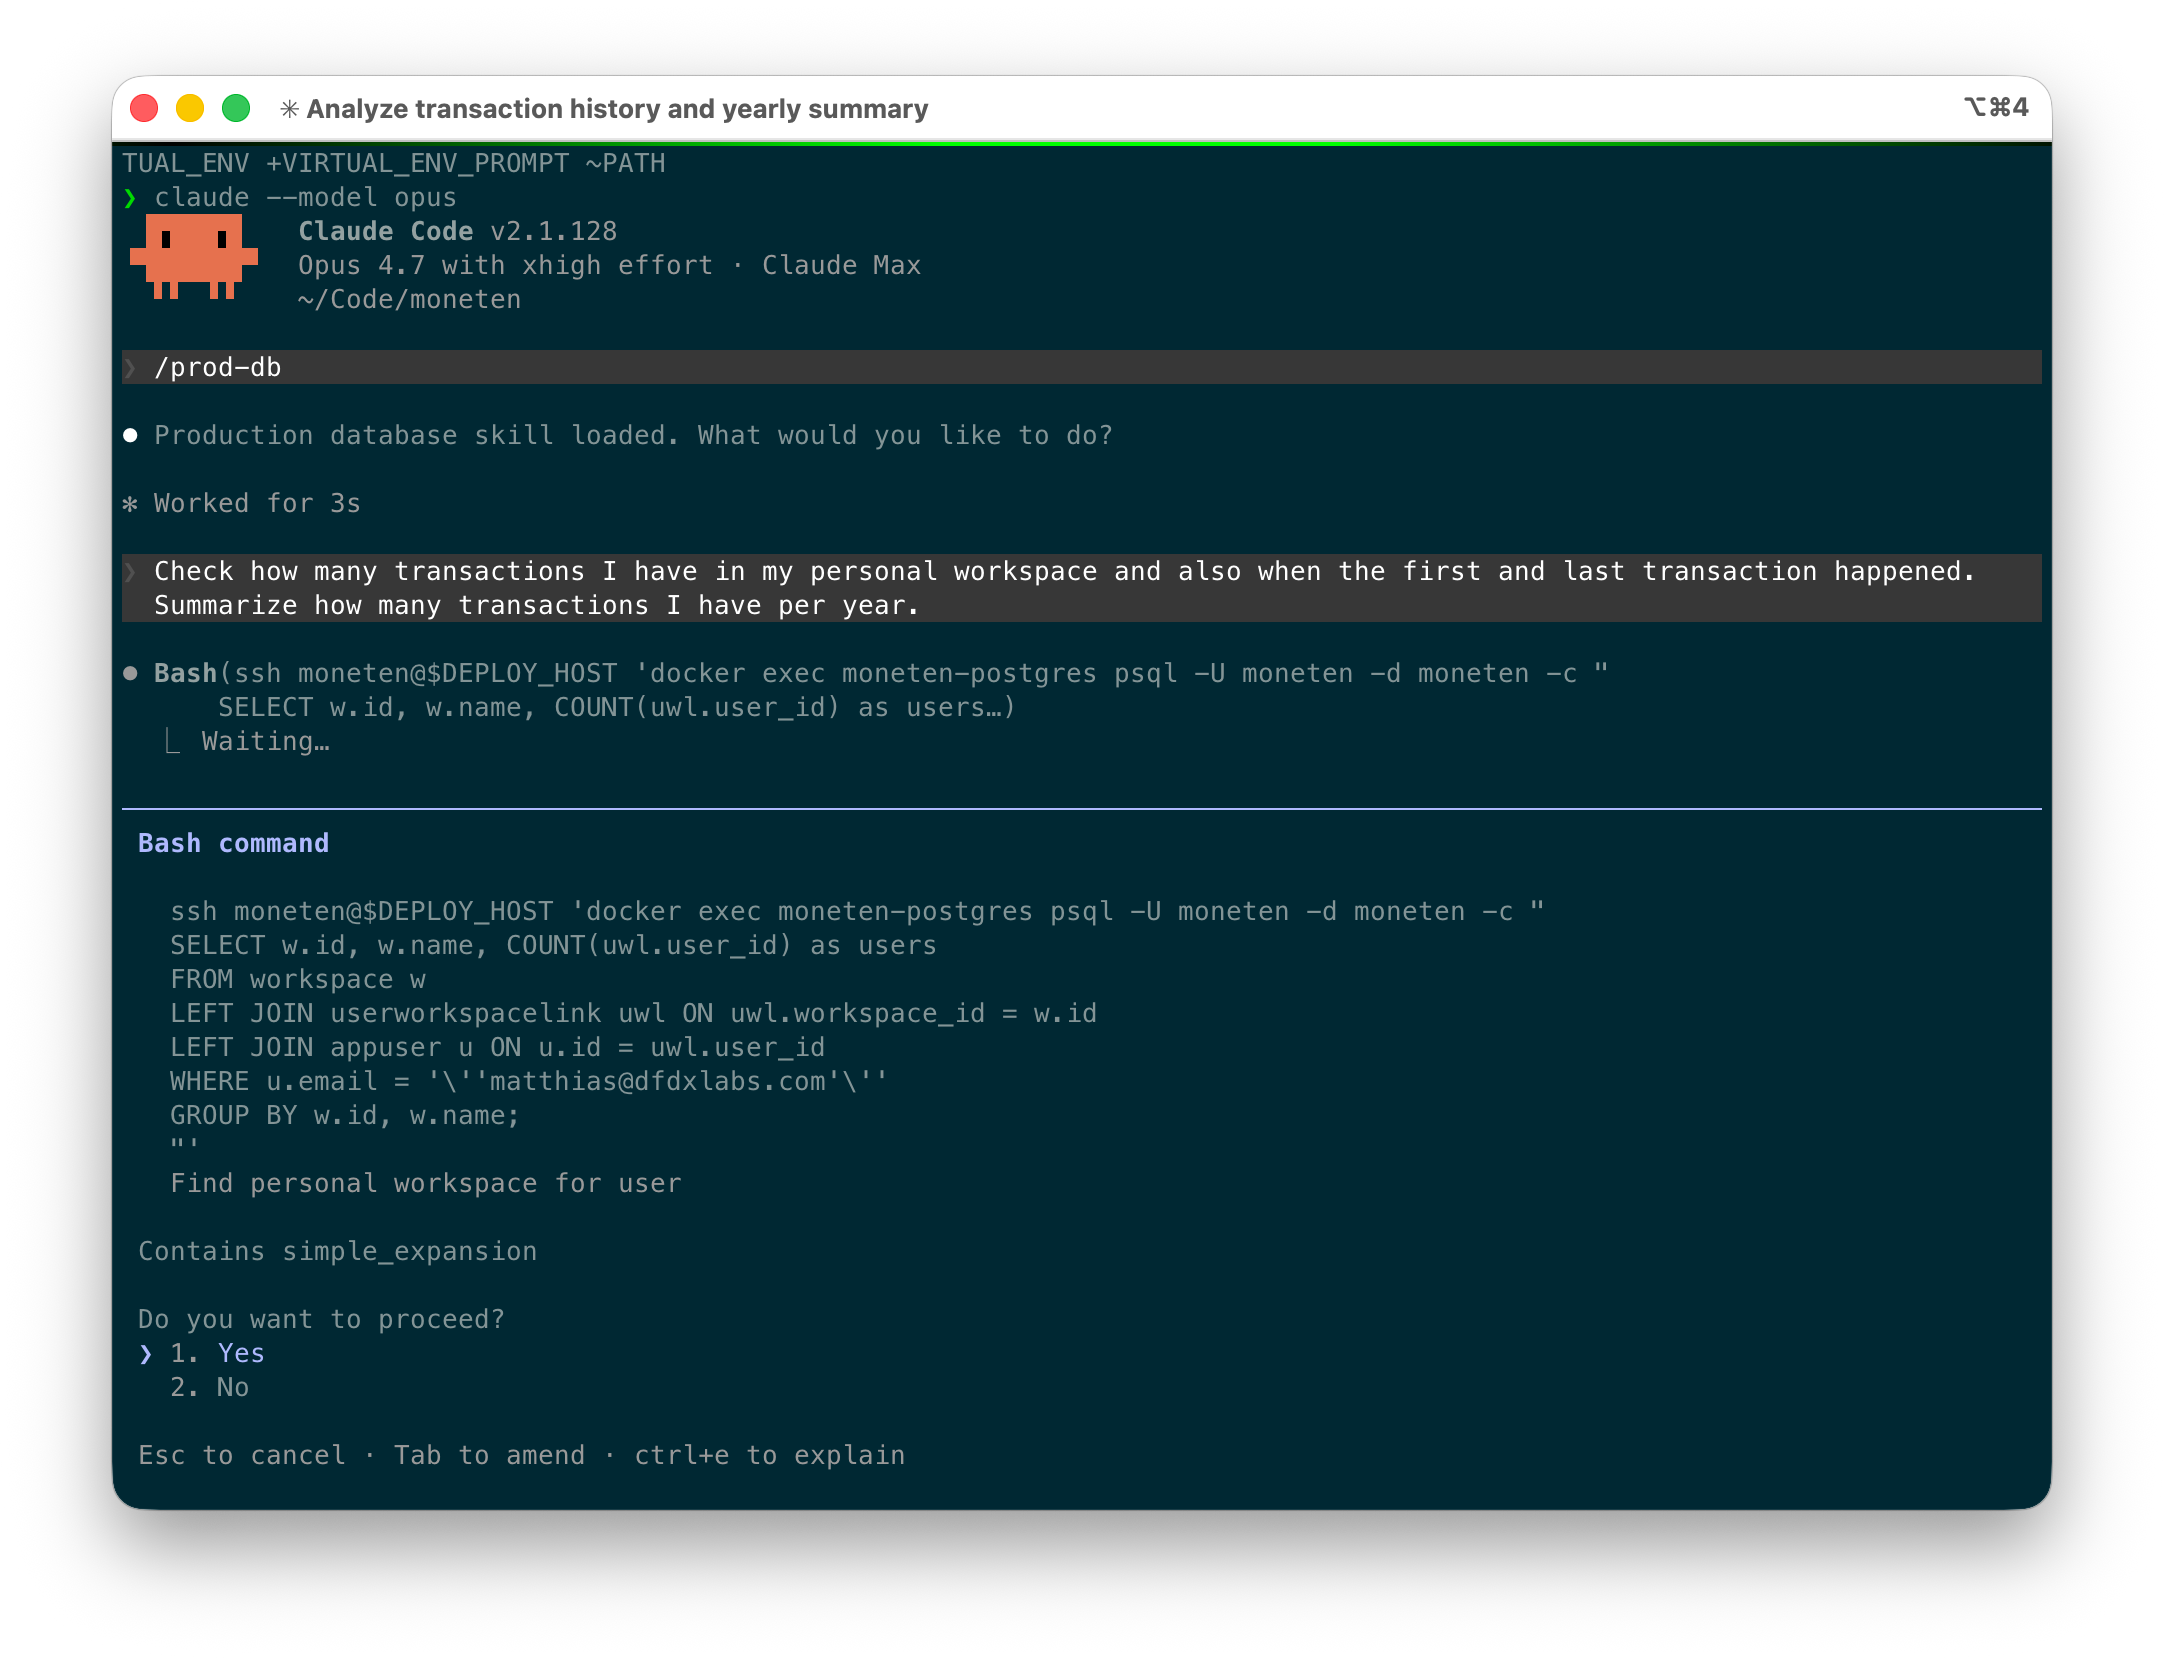
While I developed it, I had lots of missing features in the UI so I gave Claude Code access to the Postgres database and asked it to update the database accordingly (e.g. categorizing a transaction or moving a transaction to a different account). The way I do this is with a simple skill: it shows the agent how to connect to the database, describes the schema, and provides a few examples for common operations (categorizing transactions, linking transactions, counting transactions, …).

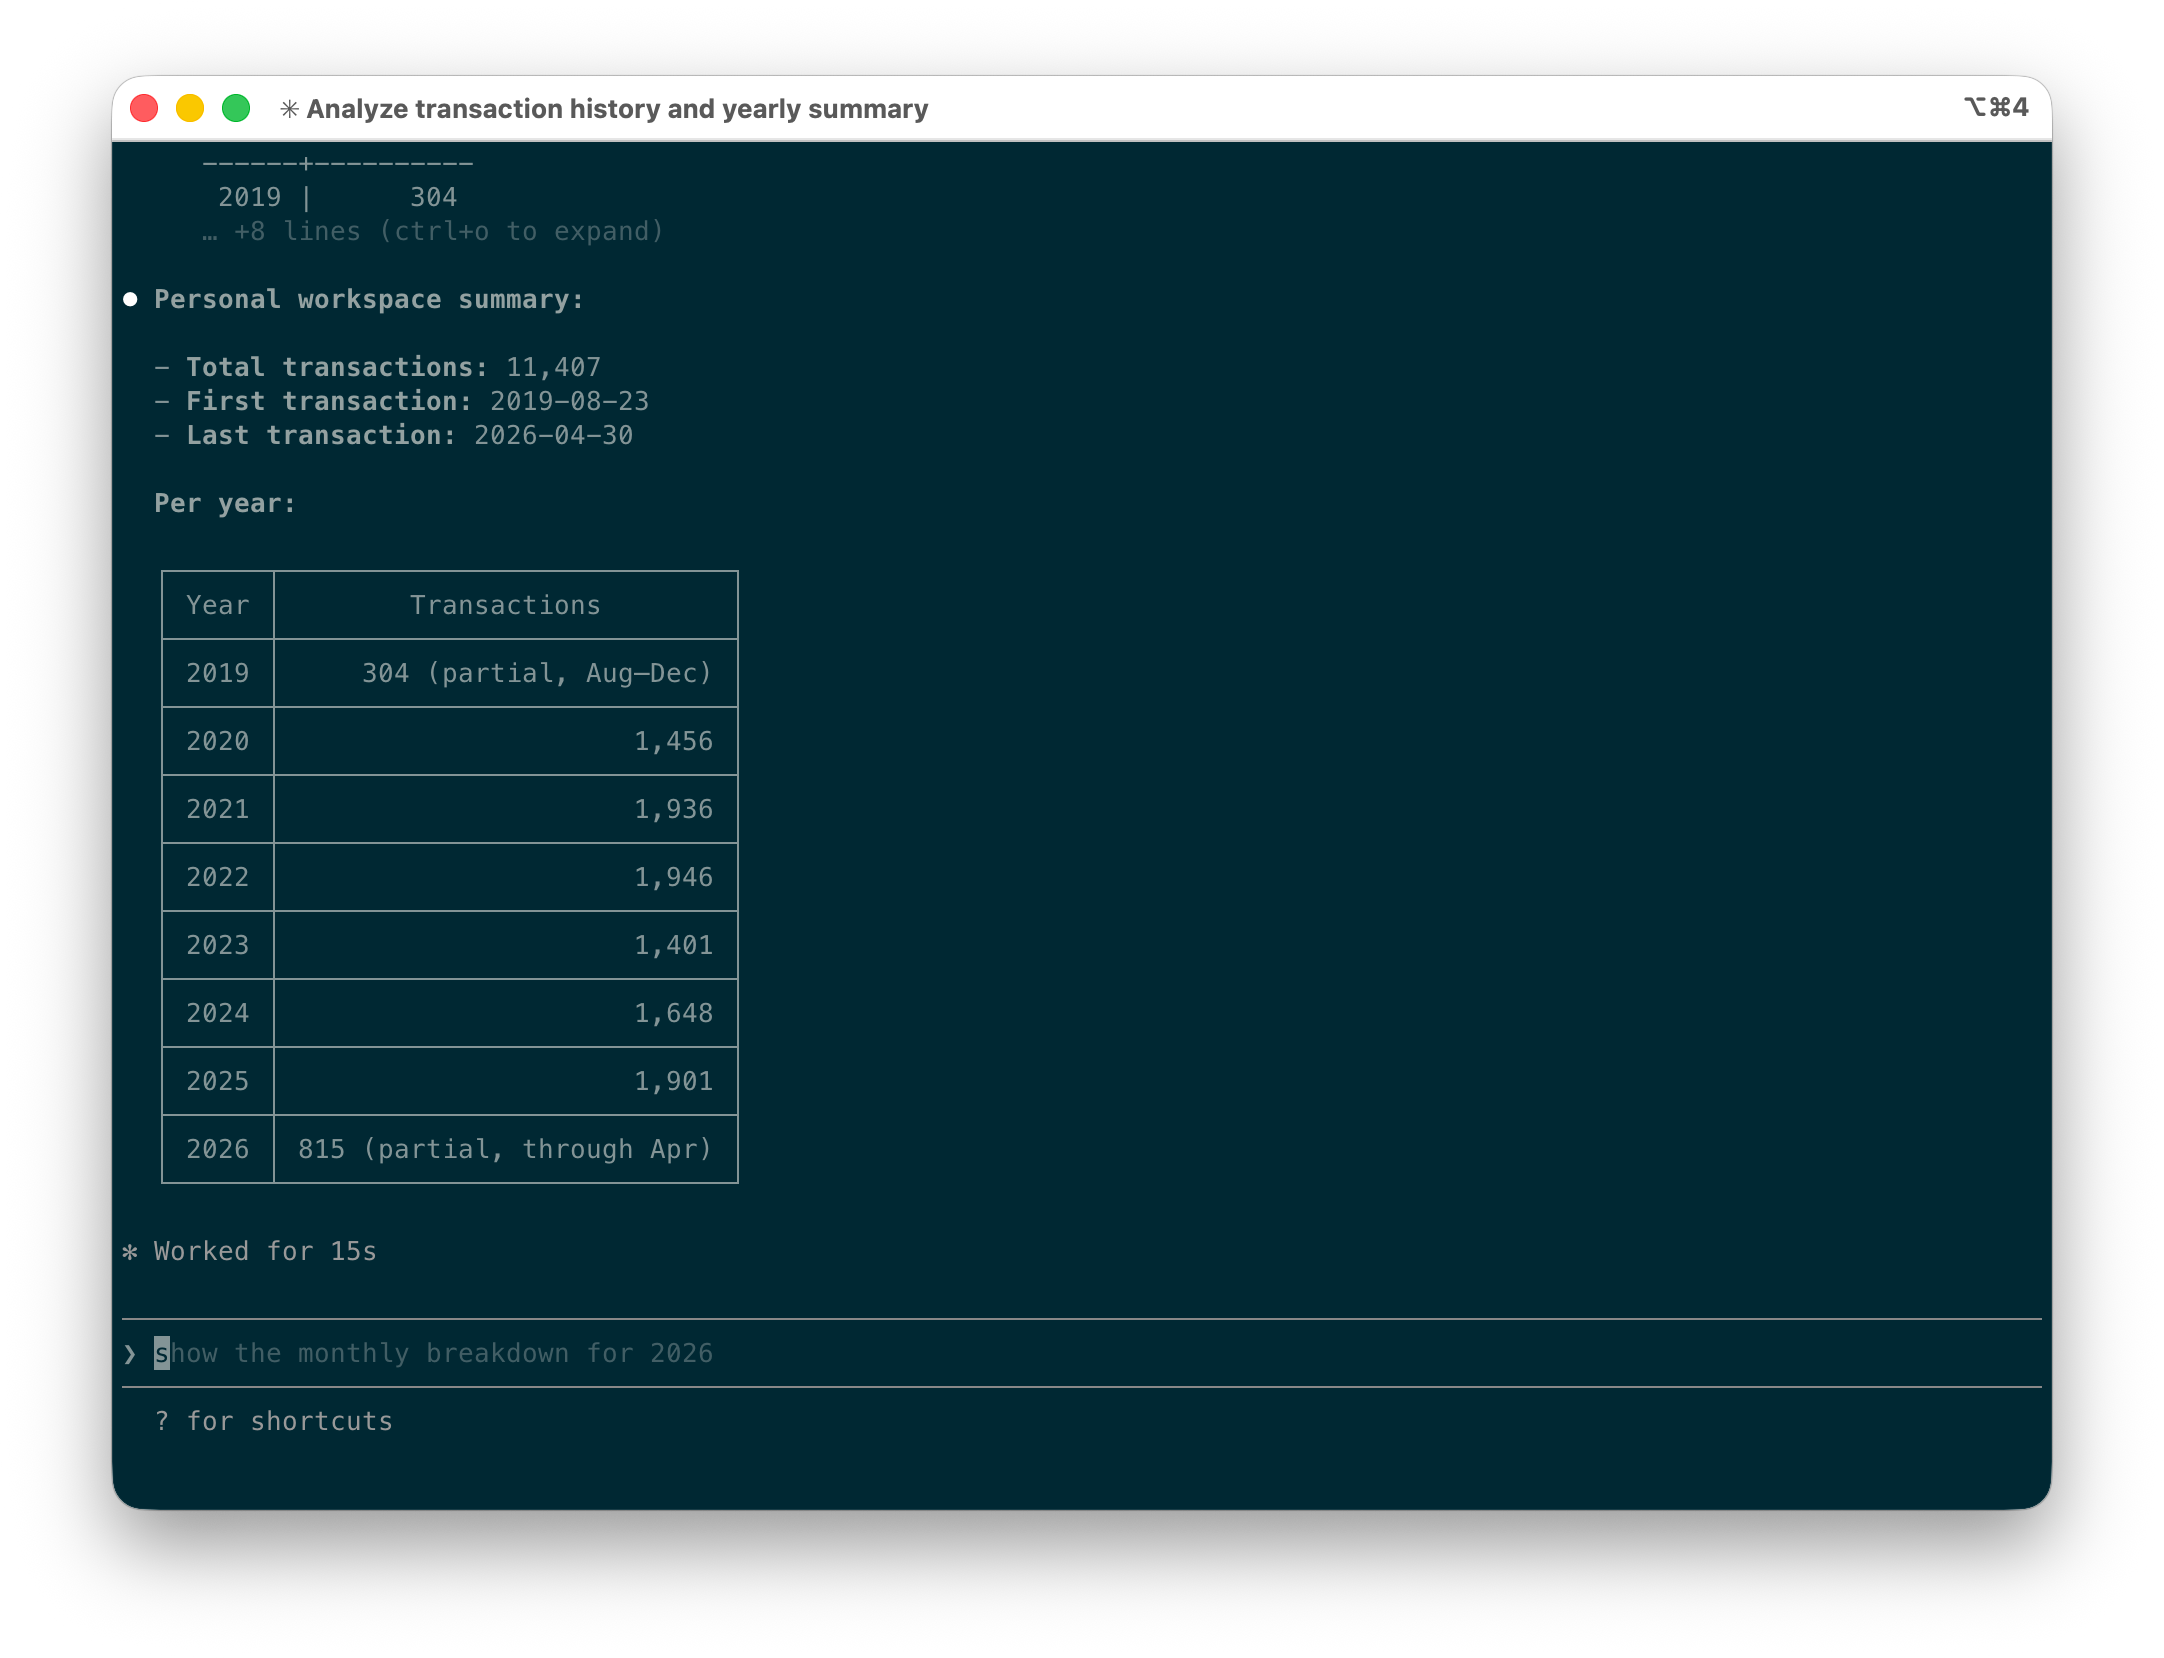
It turns out that this works amazingly well and I use it all the time now. My app has significantly progressed and most features have UI components, but it’s often easier and faster, especially for bulk operations, to use Claude Code to make changes. Below is a simple example (with the actual numbers masked for privacy reasons).

A prompt asking Claude Code to 'Check how many transactions I have in my personal workspace and also when the first and last transaction happened. Summarize how many transactions I have per year.'

Notice how Claude Code executes raw SQL queries but asks before executing them (and I make sure to review them, especially if it’s not a SELECT query). After running a few of these, Claude Code arrives at the result.

A screenshot of Claude Code returning the requested results.

So, you might say, you are giving AI access to a production database 🤨? Yes, and I have to admit it feels slightly wrong.

However, I think it works in practice for the following reasons:

  • The database only contains my own personal finance data. I would obviously never, ever do this if this were an app that is used by other people.
  • I review each SQL query before executing it. I explicitly configured Claude Code to ask for permission for the corresponding bash command.
  • I produce daily database backups and keep them around for a long time.
  • I reconcile account transactions with the balance on my bank statements regularly, so I have natural checkpoints that would uncover incorrect balances.
  • I enforce data model constraints at the database level, so the database cannot be in an inconsistent state. I think this one is key and Postgres is a great choice here with its support for triggers.

At the end of the day, I feel comfortable with the remaining risk for my use case and the benefit I get from raw database access is immense.

Imagine how much more cumbersome this would’ve been via an API: The agent would’ve had to request all transactions, then parse the date, then count them in memory. The right data model for structured data is a database.

However, I’ve noticed that I feel a lot more confident letting Claude Code edit my notes (since they are versioned under git) vs. letting it loose on my personal finance database (which is not versioned, so I need to make sure the commands it runs are reasonable).

Takeaways

AI wants to be as close as possible to your data: raw data > cli / mcp / api > gui. Local matters less than you’d think; what matters is direct access. Bear’s database is local but I can’t directly modify it, so it doesn’t help.

For unstructured data, use raw text files; coding agents are great at finding and editing them. For structured data, use raw database access; you simply can’t get the same expressiveness via a CLI or API. The database route is an obvious risk, so it only works if the database contains only your data and you trust yourself to do it responsibly.

For write access, you either review and approve every AI change, or you need versioning so you can see what changed and revert. For text files this is solved: just use git. For databases it’s largely unsolved in the mainstream. Dolt shows it’s possible—a MySQL-compatible database with git-style branching, diffing, and merging on row data—but nothing comparable exists for Postgres or SQLite, where most personal data actually lives. There’s ample opportunity for more innovation here.

Footnotes

  1. When I started experimenting with this, the only way to write back notes into Bear was via their URL schema. This turned out to be extremely cumbersome (you need to pass the entire note) and worked very poorly for batch processing (Bear opens every time the URL gets called). ↩︎

  2. You could of course write some code that maps from source → temporary file → apply changes → source, but at that point why are we not just using files in the first place? ↩︎

You have to earn your calculator

| 2 min read | Permalink

In 6th grade, all we wanted was a calculator. In my German school, you got to use them starting in 7th grade, and we were very jealous of the older kids. Why were we still doing math by hand when next year we’d have a machine for it?

When we complained, my math teacher responded: “Yes, there are calculators. Yes, they will make your lives easier. But you have to earn them first.”

He was right, of course. When you do something by hand, you build intuition that the shortcut can’t give you. The calculator is better at computing than you’ll ever be. But it can’t tell you what to compute, or what the result means. You only develop that judgment by doing the work yourself.

Once we’d earned it, of course we used the calculator. That’s the whole point. It shifts the work away from mechanical computation to the interesting part—what the math actually means.

Now I have LLMs. They’re the most powerful tool I’ve ever had, especially for programming. I use them heavily and I don’t want to go back.

But I still remember my math teacher. When I’ve written this type of code a million times, or it’s boilerplate, or the code is just a means to an end—I let the LLM do it. I’ve already earned that.

When I’m learning something new, or doing research, I write the code myself. Not because I’m old-fashioned. Because when I skip the struggle, I don’t build the intuition. I can’t see the shape of the problem. I don’t know what to try next. I don’t notice the questions and choices that naturally come up while writing the code. The understanding is the work, and there’s no shortcut to it.

The trouble is that we’re all in school again, with an amazingly powerful calculator but without a teacher to hold us accountable. Nobody’s going to make you earn it. That’s on you.

Deepfakes for code and the asymmetric internet

| 4 min read | Permalink

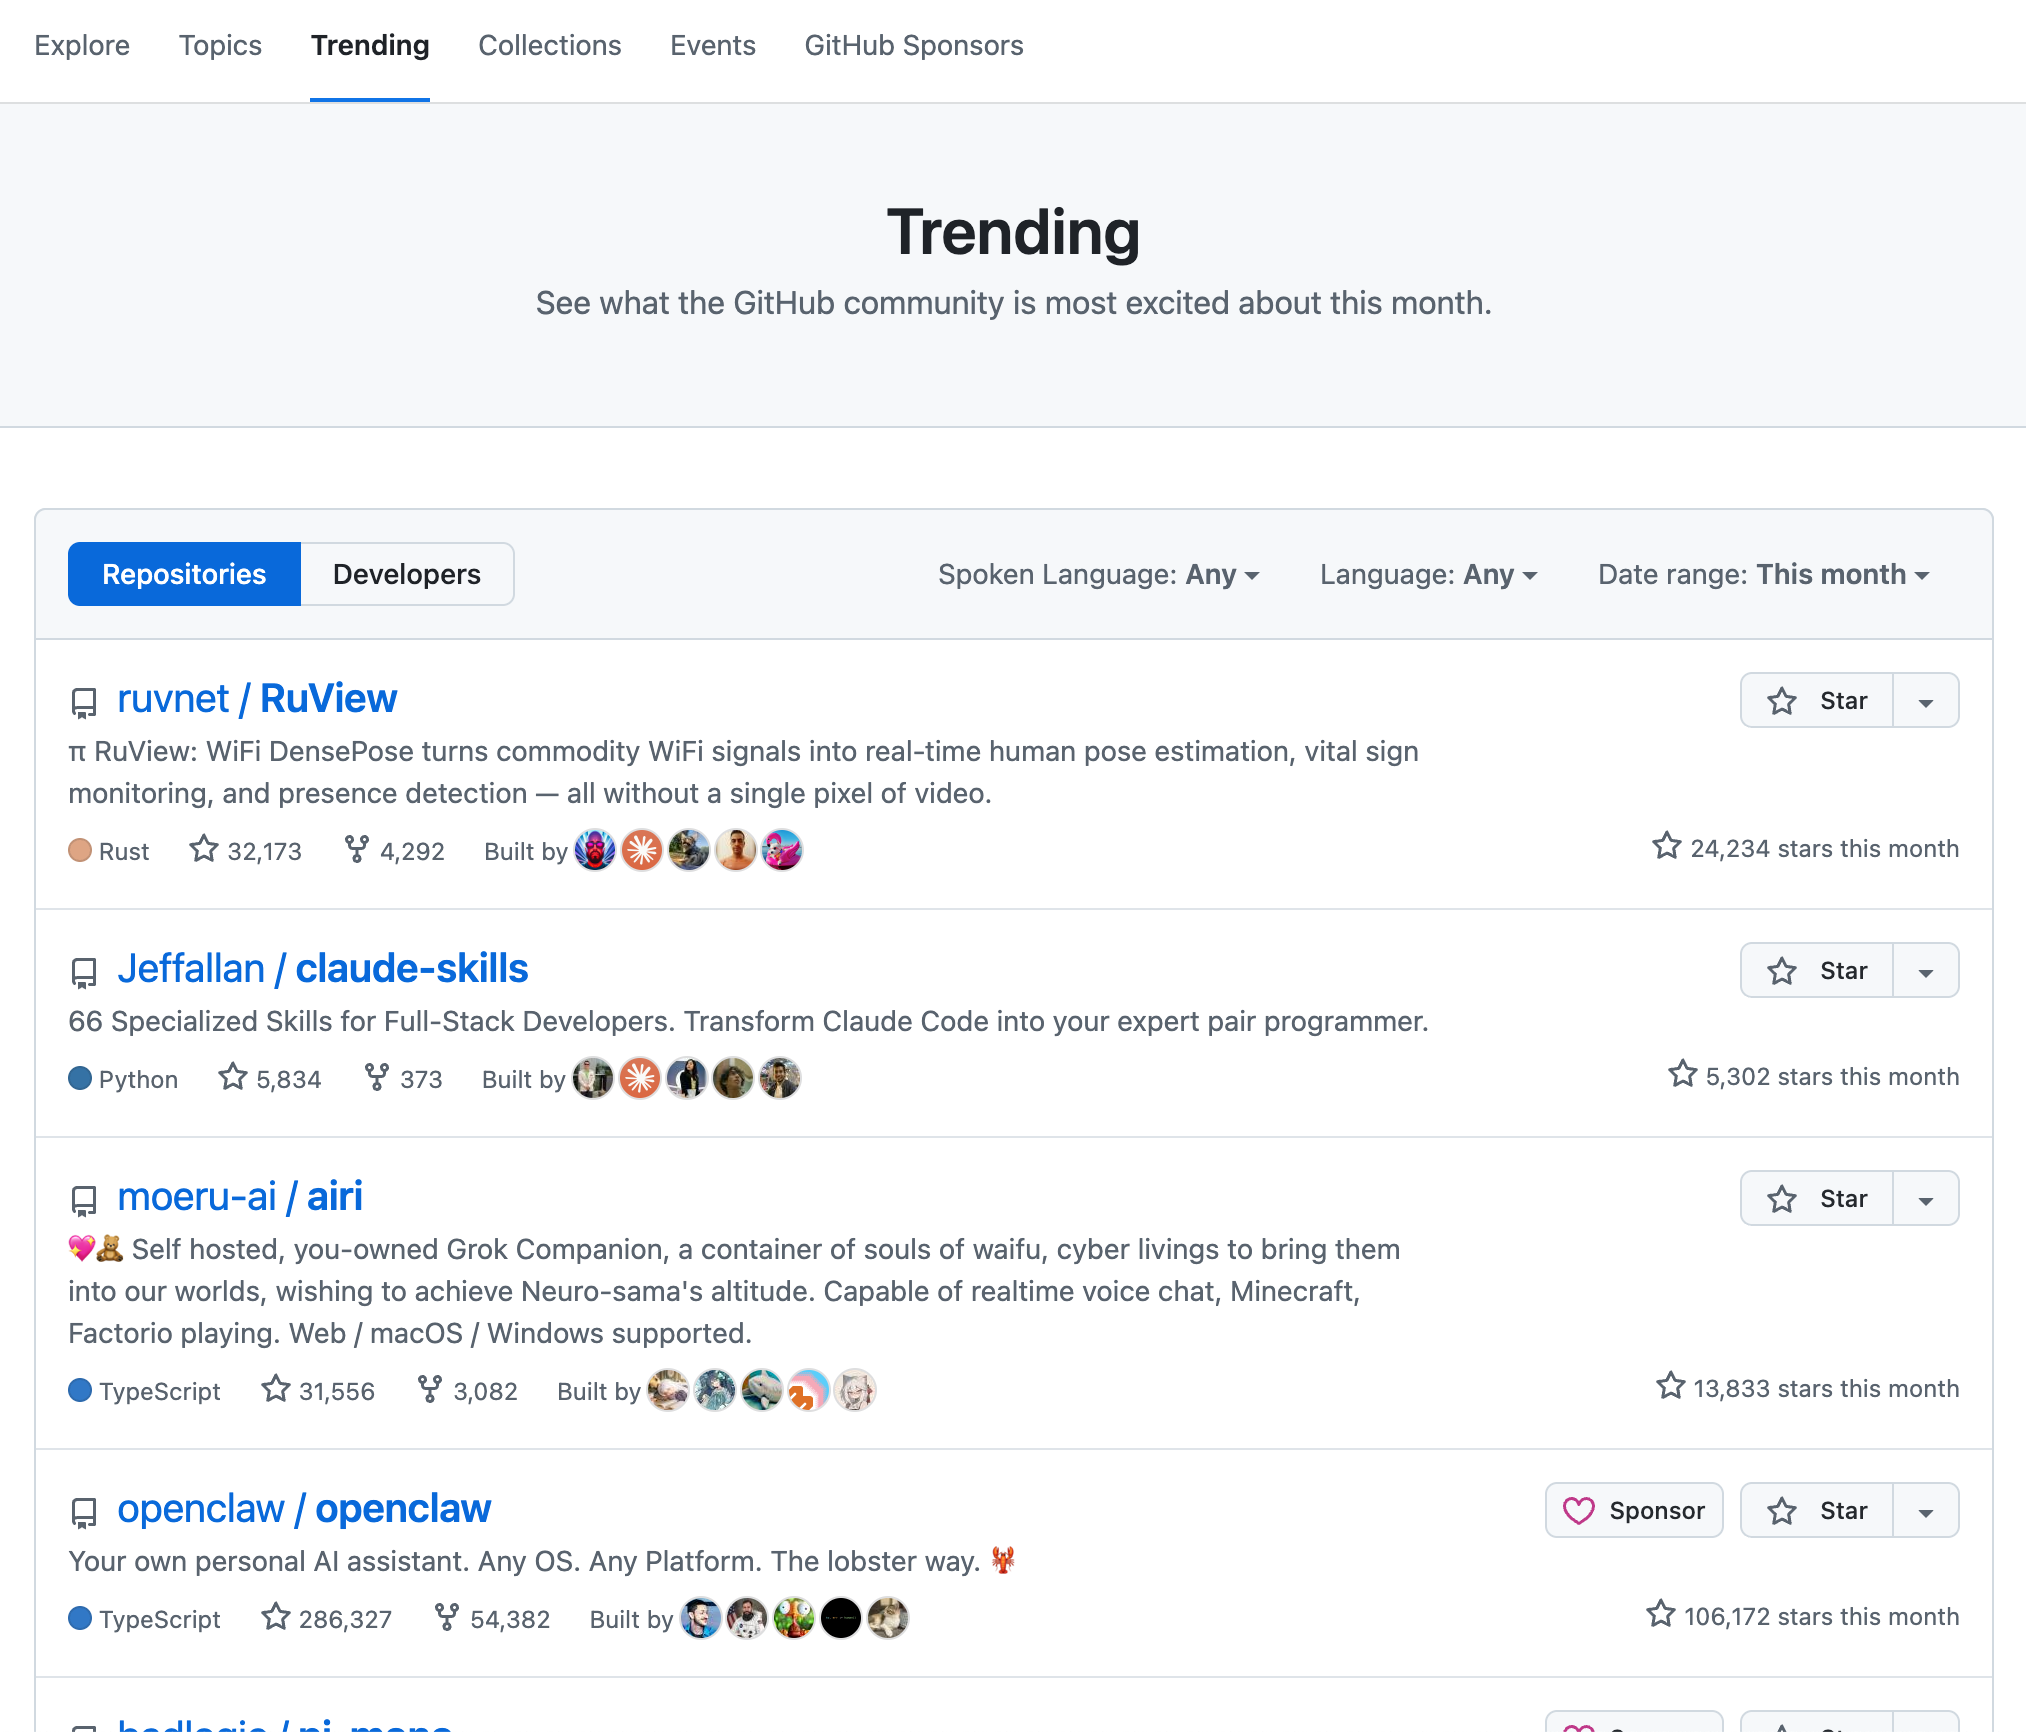
I recently came across a GitHub repo that I found fascinating. It’s called ruvnet/RuView; it has ~29k stars and is the #1 trending repo for this month as of this writing. It claims to turn commodity WiFi signals into real-time human pose estimation and vital sign monitoring (the idea is real and based on actual research). It made the rounds on social media. People on Reddit are even asking how to protect themselves against it.

RuView trending on GitHub
RuView is the #1 trending repo on GitHub this month even though it doesn't do anything useful.

This particular repo, however, does nothing useful. The project’s “pose estimation” is a hardcoded skeleton template wiggled by sine waves, and with a hard-coded walking animation. Before the author rewrote (obscured?) everything in Rust, this was even clearer: The code that was supposed to return data from the WiFi sensor returned random numbers.

It’s essentially a deepfake, but for code. There’s plausible-looking Rust and Python code, a convincing README, all the right buzzwords. It looks real enough to fool thousands of developers into starring it.

This isn’t an isolated incident; the author has over a hundred similar repos on their GitHub, all of them seemingly AI-generated.1

These repos are symptoms of something more fundamental. The internet always made it cheap to distribute noise—spam and SEO clickbait have been around for decades. But AI has made it cheap to produce convincing noise too. A single person can now mass-produce plausible-looking repos, articles, and images at near-zero marginal cost. And every receiver pays the verification cost—cross-referencing, fact-checking, checking if code actually works—independently.

But AI doesn’t just increase the noise. It simultaneously makes it possible to extract signal at scale. The same technology creates the noise and powers the filter—but only for those who can afford it.

Consider Meta. They’ve invested billions in AI infrastructure for ad targeting. Apple’s App Tracking Transparency (ATT) made it significantly harder to track users across apps, degrading the signal that advertisers rely on. In response Meta built models to infer user intent and behavior from noisier data—and it worked: by Q4 2023 they were reporting record revenue of $40B, up 25% year-over-year, and completely recovered from a brutal 2022.

On the Q3 2025 earnings call, Zuckerberg said:

But any compute that we don’t need for [AI research], we feel pretty good that we’re going to be able to absorb a very large amount of that to just convert into more intelligence and better recommendations in our family of apps and ads in a profitable way.

Meta has essentially built industrial-grade signal extraction for their advertising channel—and they think it will keep getting better the more compute they can throw at it.

ATT, it turns out, was a gift in disguise for Meta. If ad targeting becomes harder due to noise, the companies that are best at signal extraction gain a more defensible moat. The increasing noise actually helps incumbents by raising the bar beyond what smaller players can afford. This is happening for Meta and I expect the same dynamic to play out in financial markets, intelligence, and anywhere else that extracting signal from noisy data confers an advantage.

This asymmetry is structural—it follows directly from the economics of AI deployment. Building and running sophisticated models for signal extraction is expensive while the cost of noise generation is approaching zero. So we end up with a world where only well-resourced actors—large tech companies, governments, sophisticated financial firms—can afford verification at scale. For the average user, the utility of the internet degrades. For smaller companies, it becomes increasingly difficult to compete. This should worry anybody who wants an open and egalitarian internet.

Footnotes

  1. I don’t know why these were produced. Maybe it’s a marketing scheme—the author offers their consultancy services for $1,500/hour. ↩︎

Browse the full archive →